Analysis
NVIDIA’s October 27 technical post describes GPU sharing with an enforceable memory allowance in CUDA 13.4. A workload can have a fixed amount or a guaranteed request with room to grow when capacity is available. That addresses a practical obstacle to packing smaller jobs together: an allocation needs to mean something when another process becomes hungry.
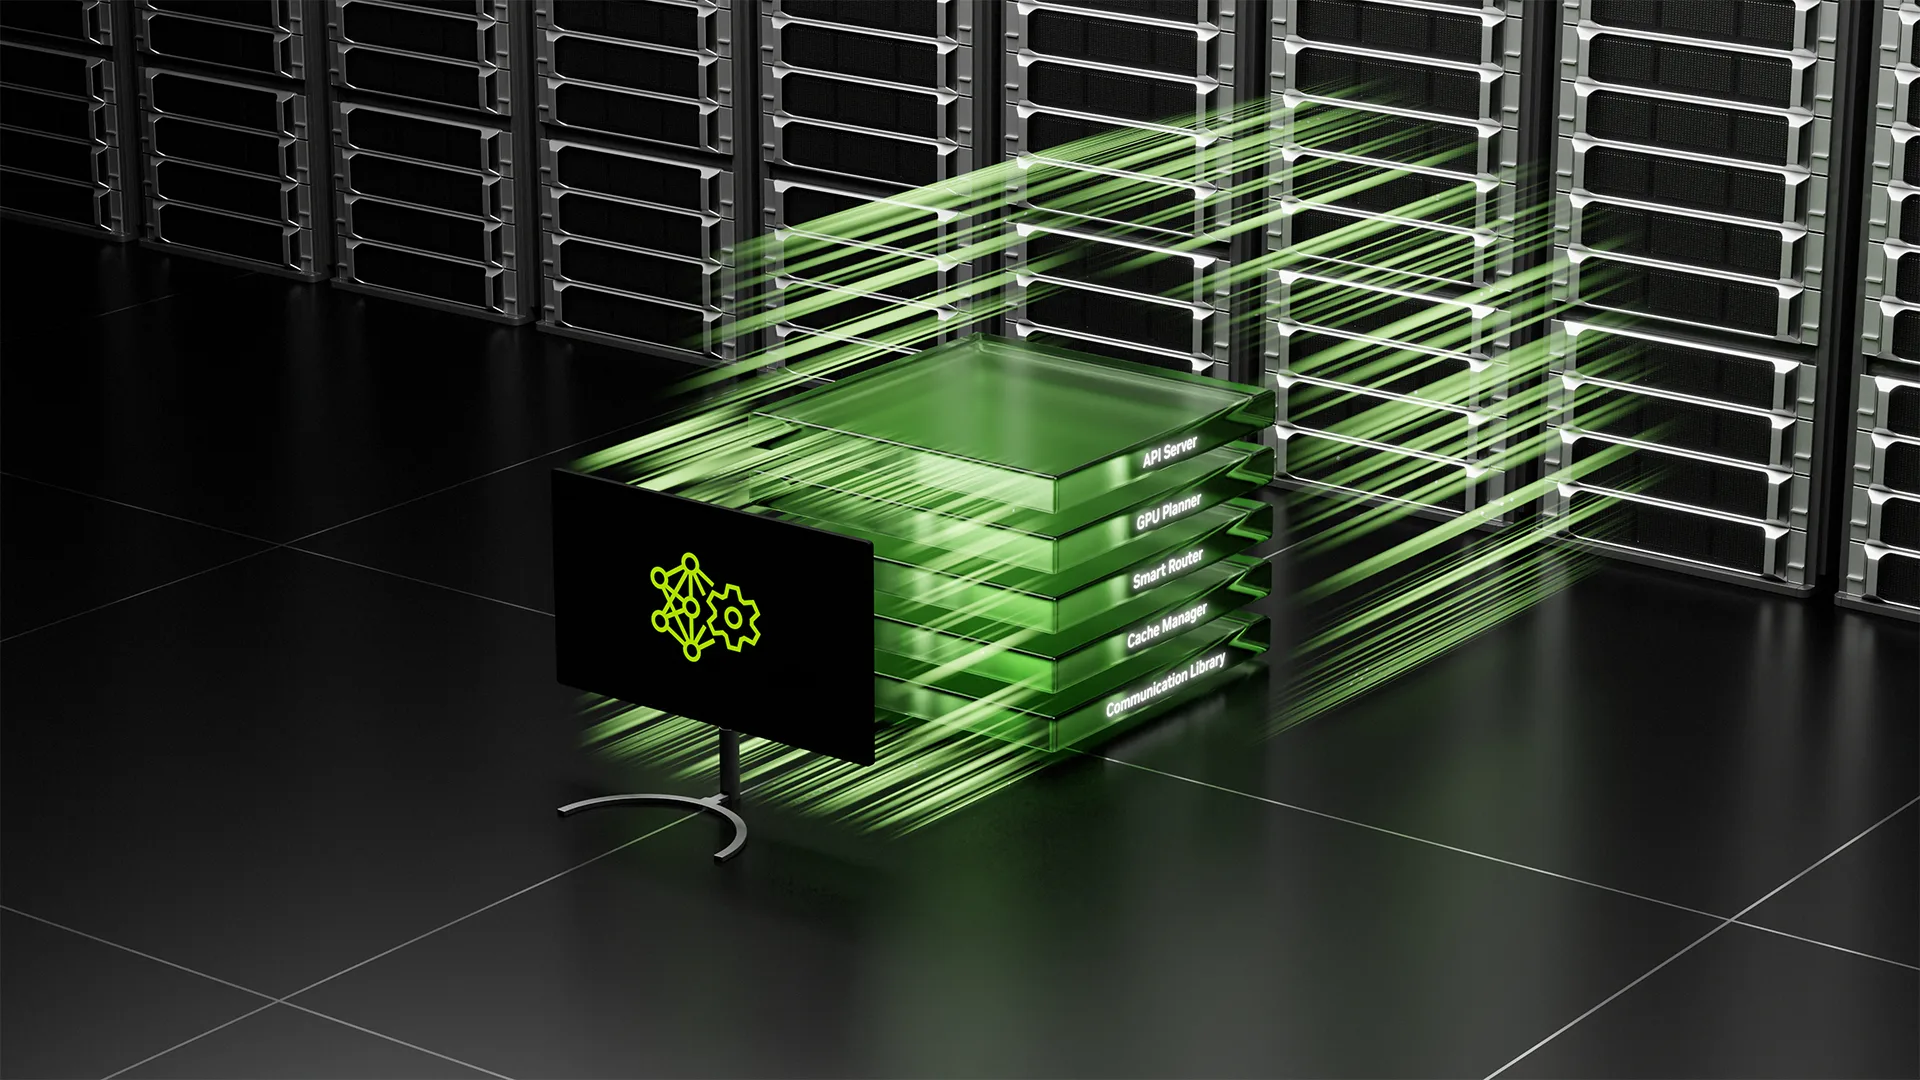
The Kubernetes machinery has separate responsibilities. The scheduler chooses devices and records allocations; the open-source GPU Fractioning Operator supervises MPS on nodes, applies workload limits and measures each fraction. NVIDIA identifies KAI Scheduler 0.18.0 as the first integration, using its NvFractions mode. Installing CUDA alone does not complete that chain.
Compute sharing also carries a consequential choice. NVIDIA describes time-slicing with separate error domains and simultaneous SM-sharing with a shared error domain. Both have memory limits, but the latter is intended for workloads trusted to run together. A memory allowance should therefore not be read as a blanket claim that every kind of failure is isolated.
The useful operational test is what happens under contention. Measure latency when neighbors are busy, check failed allocations, and verify that monitoring reports the workload’s fraction. Denser placement is attractive only if the service remains predictable. The post explains mechanisms and configuration; it does not supply an independent demonstration of savings or reliability for a particular cluster.
Source: Memory-Enforced GPU Sharing in Kubernetes with NVIDIA CUDA 13.4 · 2026-10-27
Why it matters
GPU utilization and predictable service have to improve together; a fraction is only useful when its limits and failure behavior are understood.