Analysis
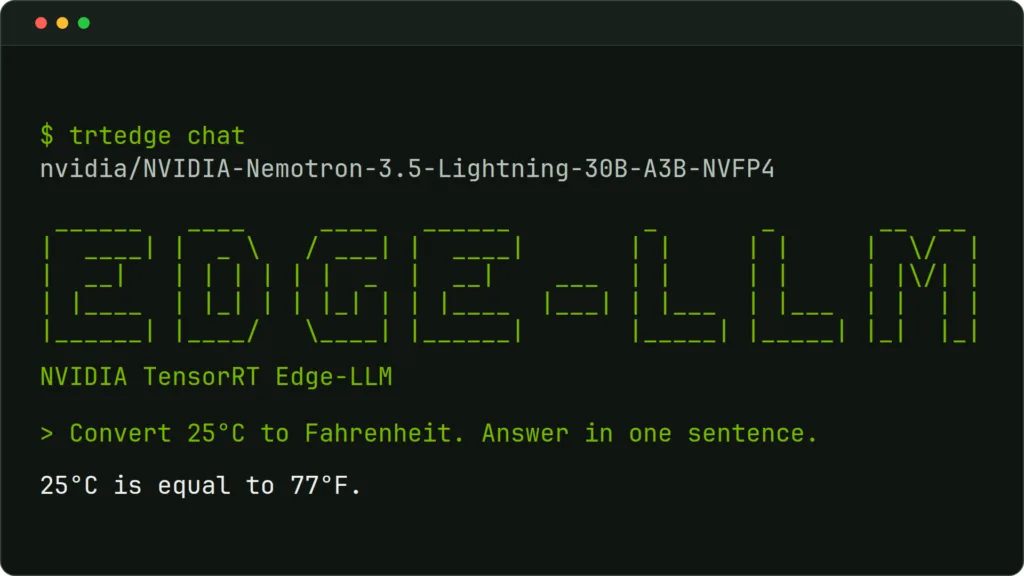
NVIDIA showed on October 30 how its TensorRT Edge-LLM runtime, version 0.11.1 with its trtedge command line, can install, chat with and serve Nemotron-3.5 Lightning, a text-only 30B-A3B model in NVFP4, from a DGX Spark. The serve command exposes an OpenAI-compatible API, and a separate readiness endpoint confirms when it is up. Deployment targets include Jetson Thor, DRIVE AGX Thor and IGX Thor.
The post reports that DSpark speculative decoding with three draft tokens raised mean generation speed from 73.4 to 126.9 tokens per second on HumanEval, and by roughly 45 to 48 percent on two SpeedBench sets, while time to first token stayed near 98 milliseconds on HumanEval and about 200 to 330 milliseconds on the SpeedBench sets. Peak system memory with speculative decoding was 27.9 GB, including the operating system. The first launch downloads about 21 GB and builds an engine.
Our reading: the measurement conditions are the story as much as the speedup. NVIDIA tested batch size one, a single streaming request, a 128-token output limit and thinking enabled. That is a reasonable profile for an on-device assistant, and it is a poor guide for a shared service or for long answers. Speculative decoding gains also depend on how predictable the workload is.
A team evaluating the runtime should reproduce the reported numbers on its own prompts first, then change one condition at a time: longer outputs, concurrent requests, and the actual target device rather than the development box. The few-command setup lowers the cost of that experiment; it does not replace it.
Source: Run AI Models for Edge Application Development with Just a Few Commands · 2026-10-30
Why it matters
Edge AI decisions depend on latency and memory under the device’s real workload, which a narrow benchmark can only approximate.