Analysis
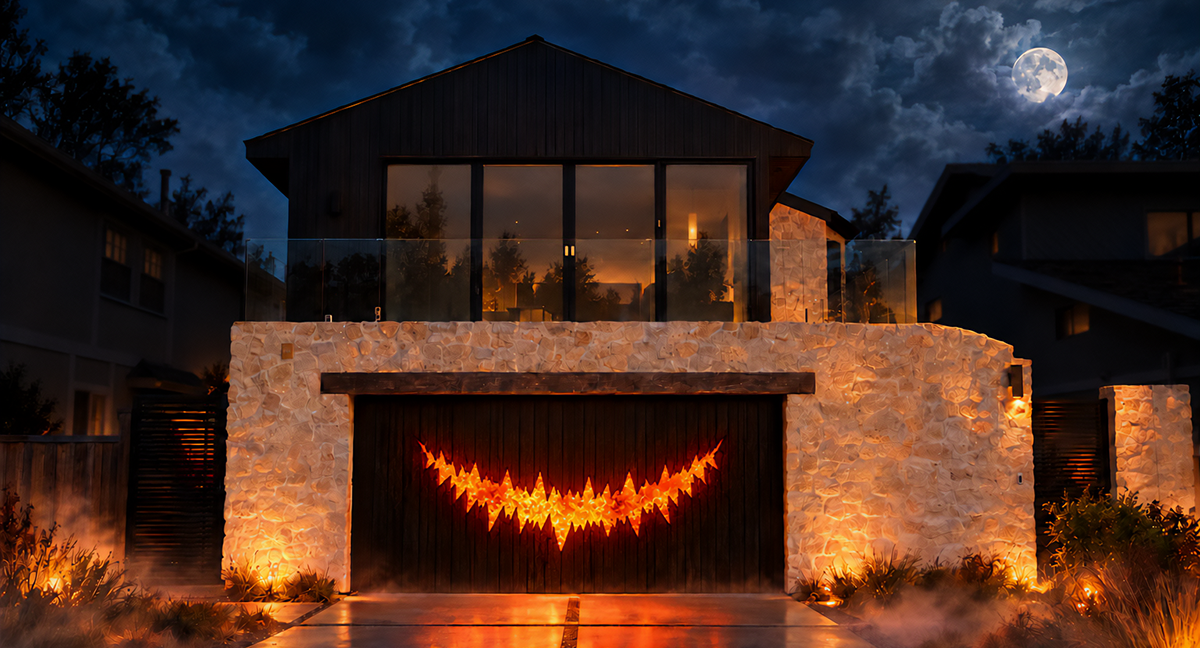
NVIDIA published a builder’s account on Hugging Face on October 30 of MonsterHouse, an interactive Halloween projection in which a garage door plays a grumpy pirate-ship character for trick-or-treaters. The character softens when visitors say “please” or “thank you.” The stack starts from the NVIDIA Nemotron Voice Agent and runs on a single workstation.
The parts are specific. Nemotron 3 streaming ASR handles speech recognition. A Nemotron 3.5 Bolt E4B model, given its personality through a LoRA adapter trained on reviewed example conversations from a dataset of more than 5,000, writes the replies. Magpie TTS Zeroshot supplies the voice and Audio2Face-3D animates the mouth. The author reports testing more than a dozen models before choosing Bolt, and a median of 1.70 seconds from the end of a visitor’s speech to the character’s audio, or 0.72 seconds for cached lines.
Our reading: the interesting number is the latency, not the model size. A spoken character feels alive only if it answers before the visitor walks away, and the build spends real effort on that: a 300-millisecond silence threshold for end of speech, cached responses, and a 100-millisecond offset to keep the face in step with the voice. A smaller dialogue model is what makes that budget achievable on one machine.
The account is candid about what is not yet proven. The sheep-costume test used a synthetic recording; real driveway groups, costumes and night lighting were still to be tested, and the code is not packaged for release. Anyone adapting the approach should measure response time and recognition with actual visitors, in the actual space, before deciding the character works.
Source: Building a Haunted House with NVIDIA Nemotron Open Models · 2026-10-30
Why it matters
A small model that answers inside a conversational time budget can matter more to a voice agent than a larger one that answers late.